Measure the Whole Workflow
How to measure whether an AI workflow is used, delivers value and remains reliable and economical.
On this page
A support assistant drafts a reply in seconds. The reviewer edits it and sends it. The dashboard records an accepted suggestion, but the customer later returns because the answer applied the wrong policy.
Acceptance tells you the reviewer used the suggestion. It does not tell you whether the answer was correct or the request resolved. Follow the work through review, the customer's next action and the cost of dealing with mistakes.
Establish a baseline
Before changing a workflow, describe the job, who performs it and how a useful outcome is reached. Measure enough of the current process to make a comparison: task time, quality, waiting, correction and cost where those can be observed. Record important differences in task difficulty or customer group.
For the hypothetical support workflow, the baseline might include time to a correct resolution, follow-up contacts and the effort required to check policy. The new workflow adds model and tool costs, review, escalation and recovery. Compare those with the original process over a meaningful period.
A simple before-and-after comparison can be misleading when the mix of requests or staffing changes. Where the decision warrants it, compare similar groups or run a controlled test. Treat the result as an estimate with uncertainty, not proof that every observed change came from AI.
Follow the path to value
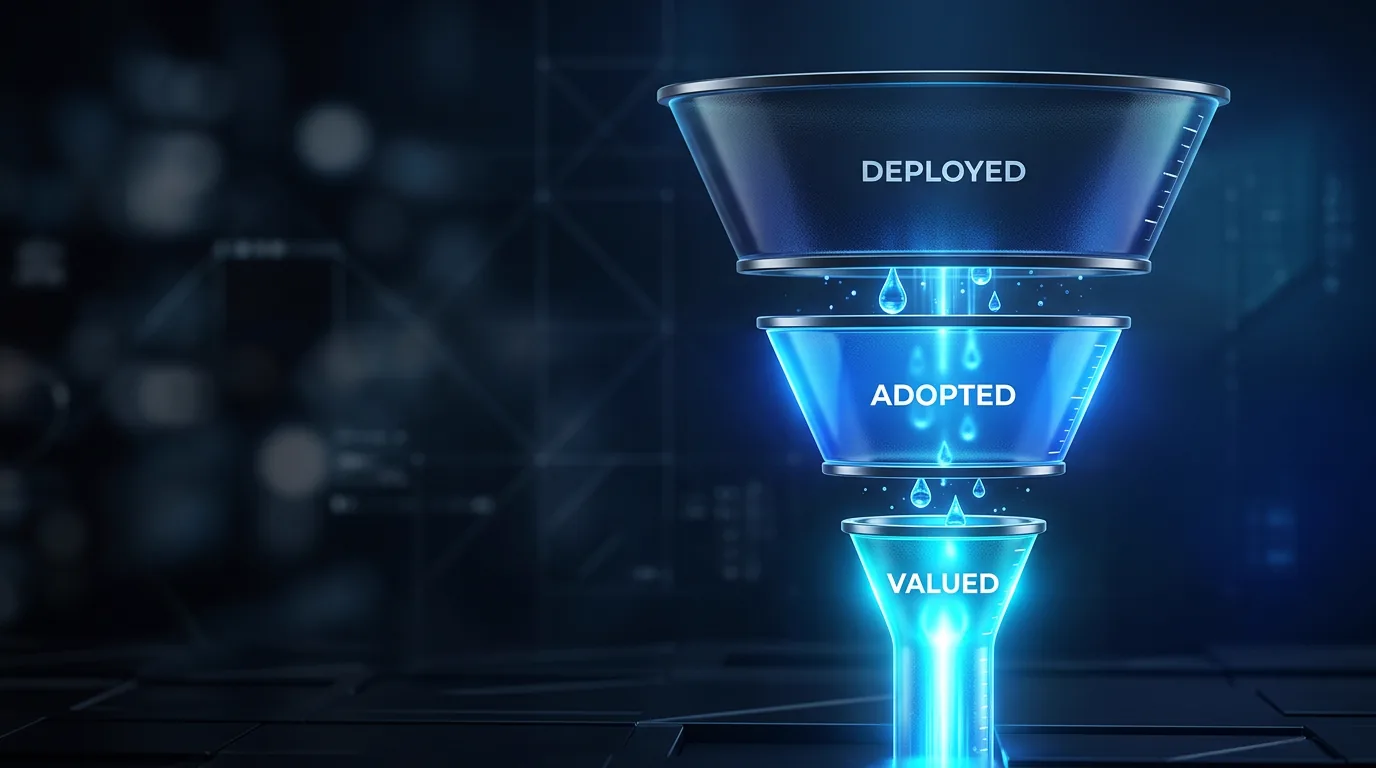
A useful measurement path has several distinct stages:
- Available: can the intended people access the capability with the context and support they need?
- Tried: do they find it and attempt the task?
- Used again: does it fit work they actually repeat?
- Valued: does it contribute to an outcome they care about without unacceptable cost or harm?
A gap can have several causes. Low use may reflect poor discovery, low relevance, lack of permission or a sensible preference for an existing method. Repeat use can coexist with poor outcomes if a team is required to use a tool. Pair analytics with observation and conversation before choosing a fix.
Check quality and review effort
Choose quality measures for the task. For a drafted response, inspect factual and policy accuracy, omissions and whether escalation was appropriate. For an agent that changes records, check the final state and the actions taken along the way. The evaluation chapter covers representative cases and grading.
Measure the work needed to make an output usable: review time, corrections, retries and escalation. Compare it with the original workflow. A shorter generation time can still produce a slower task if people have to investigate every result.
Overrides and approvals are signals, not verdicts. Frequent edits may mean the draft is weak or that users are tailoring a good starting point. Very few edits may mean the output is reliable or that reviewers are rubber-stamping. Inspect a sample against an independent quality standard.
Observe risk and recovery
Track the failures that matter: incorrect actions, privacy or security incidents, missed escalations, time to detection and successful recovery. Segment by task and consequence when an overall average would hide a serious problem.
Do not treat a model's stated confidence as a probability of correctness. A risk signal may use evidence such as missing data, a failed validation or known task characteristics, but it needs to be tested against observed outcomes before it controls review or automation.
Escalation is not automatically a failure. A system that hands off an unfamiliar case can be working as intended. Examine why cases escalate, how long they wait and whether the person receiving them can resolve the issue.
Connect measures to decisions
For each measure, name the decision it informs and who can act on it. Set a threshold from the baseline, customer need, consequence and investment case rather than a universal benchmark.
| Evidence | Possible decision |
|---|---|
| Users cannot reach the first useful outcome | Investigate access, onboarding or whether the job matters enough. |
| Quality is acceptable but review consumes the saving | Change the task boundary or interaction, then test the complete workflow again. |
| A consequential failure repeats | Pause or narrow the workflow, investigate the cause and strengthen the relevant control. |
| The outcome improves at an acceptable cost | Consider expanding the pilot, while checking whether the evidence applies to the next group. |
| A reasonable test fails to support the bet | Revise the idea or stop the investment. |
Review cadence should reflect traffic, rate of change and consequence. An actively changing service may need frequent review and immediate alerts for serious failures; a stable, low-volume workflow may need a different rhythm. Keep an owner for the measurement and the resulting decision.
v3.1 · Updated Oct 2026